Deprecation Notice 👋
This feature is deprecated and will no longer be maintained. We recommend discontinuing its use.
What does this mean for existing users?
-
Existing configurations: Requirements will continue to be indexed as before.
-
New configurations: Creating new configuration macros for Linear Document usage is no longer supported.
-
Date of removal: We will make an announcement when we see an usage decline.
What's next?
We're not giving up on the idea of indexing large documents! We're working on a new feature to provide a better solution for this use case. Stay tuned for updates!
If you have any questions just send us a ticket on this link: http://support.requirementyogi.com/
Requirement Yogi for Confluence Cloud is able to parse paragraphs and linear documents. Watch our quick tutorial:
What are “linear documents”?
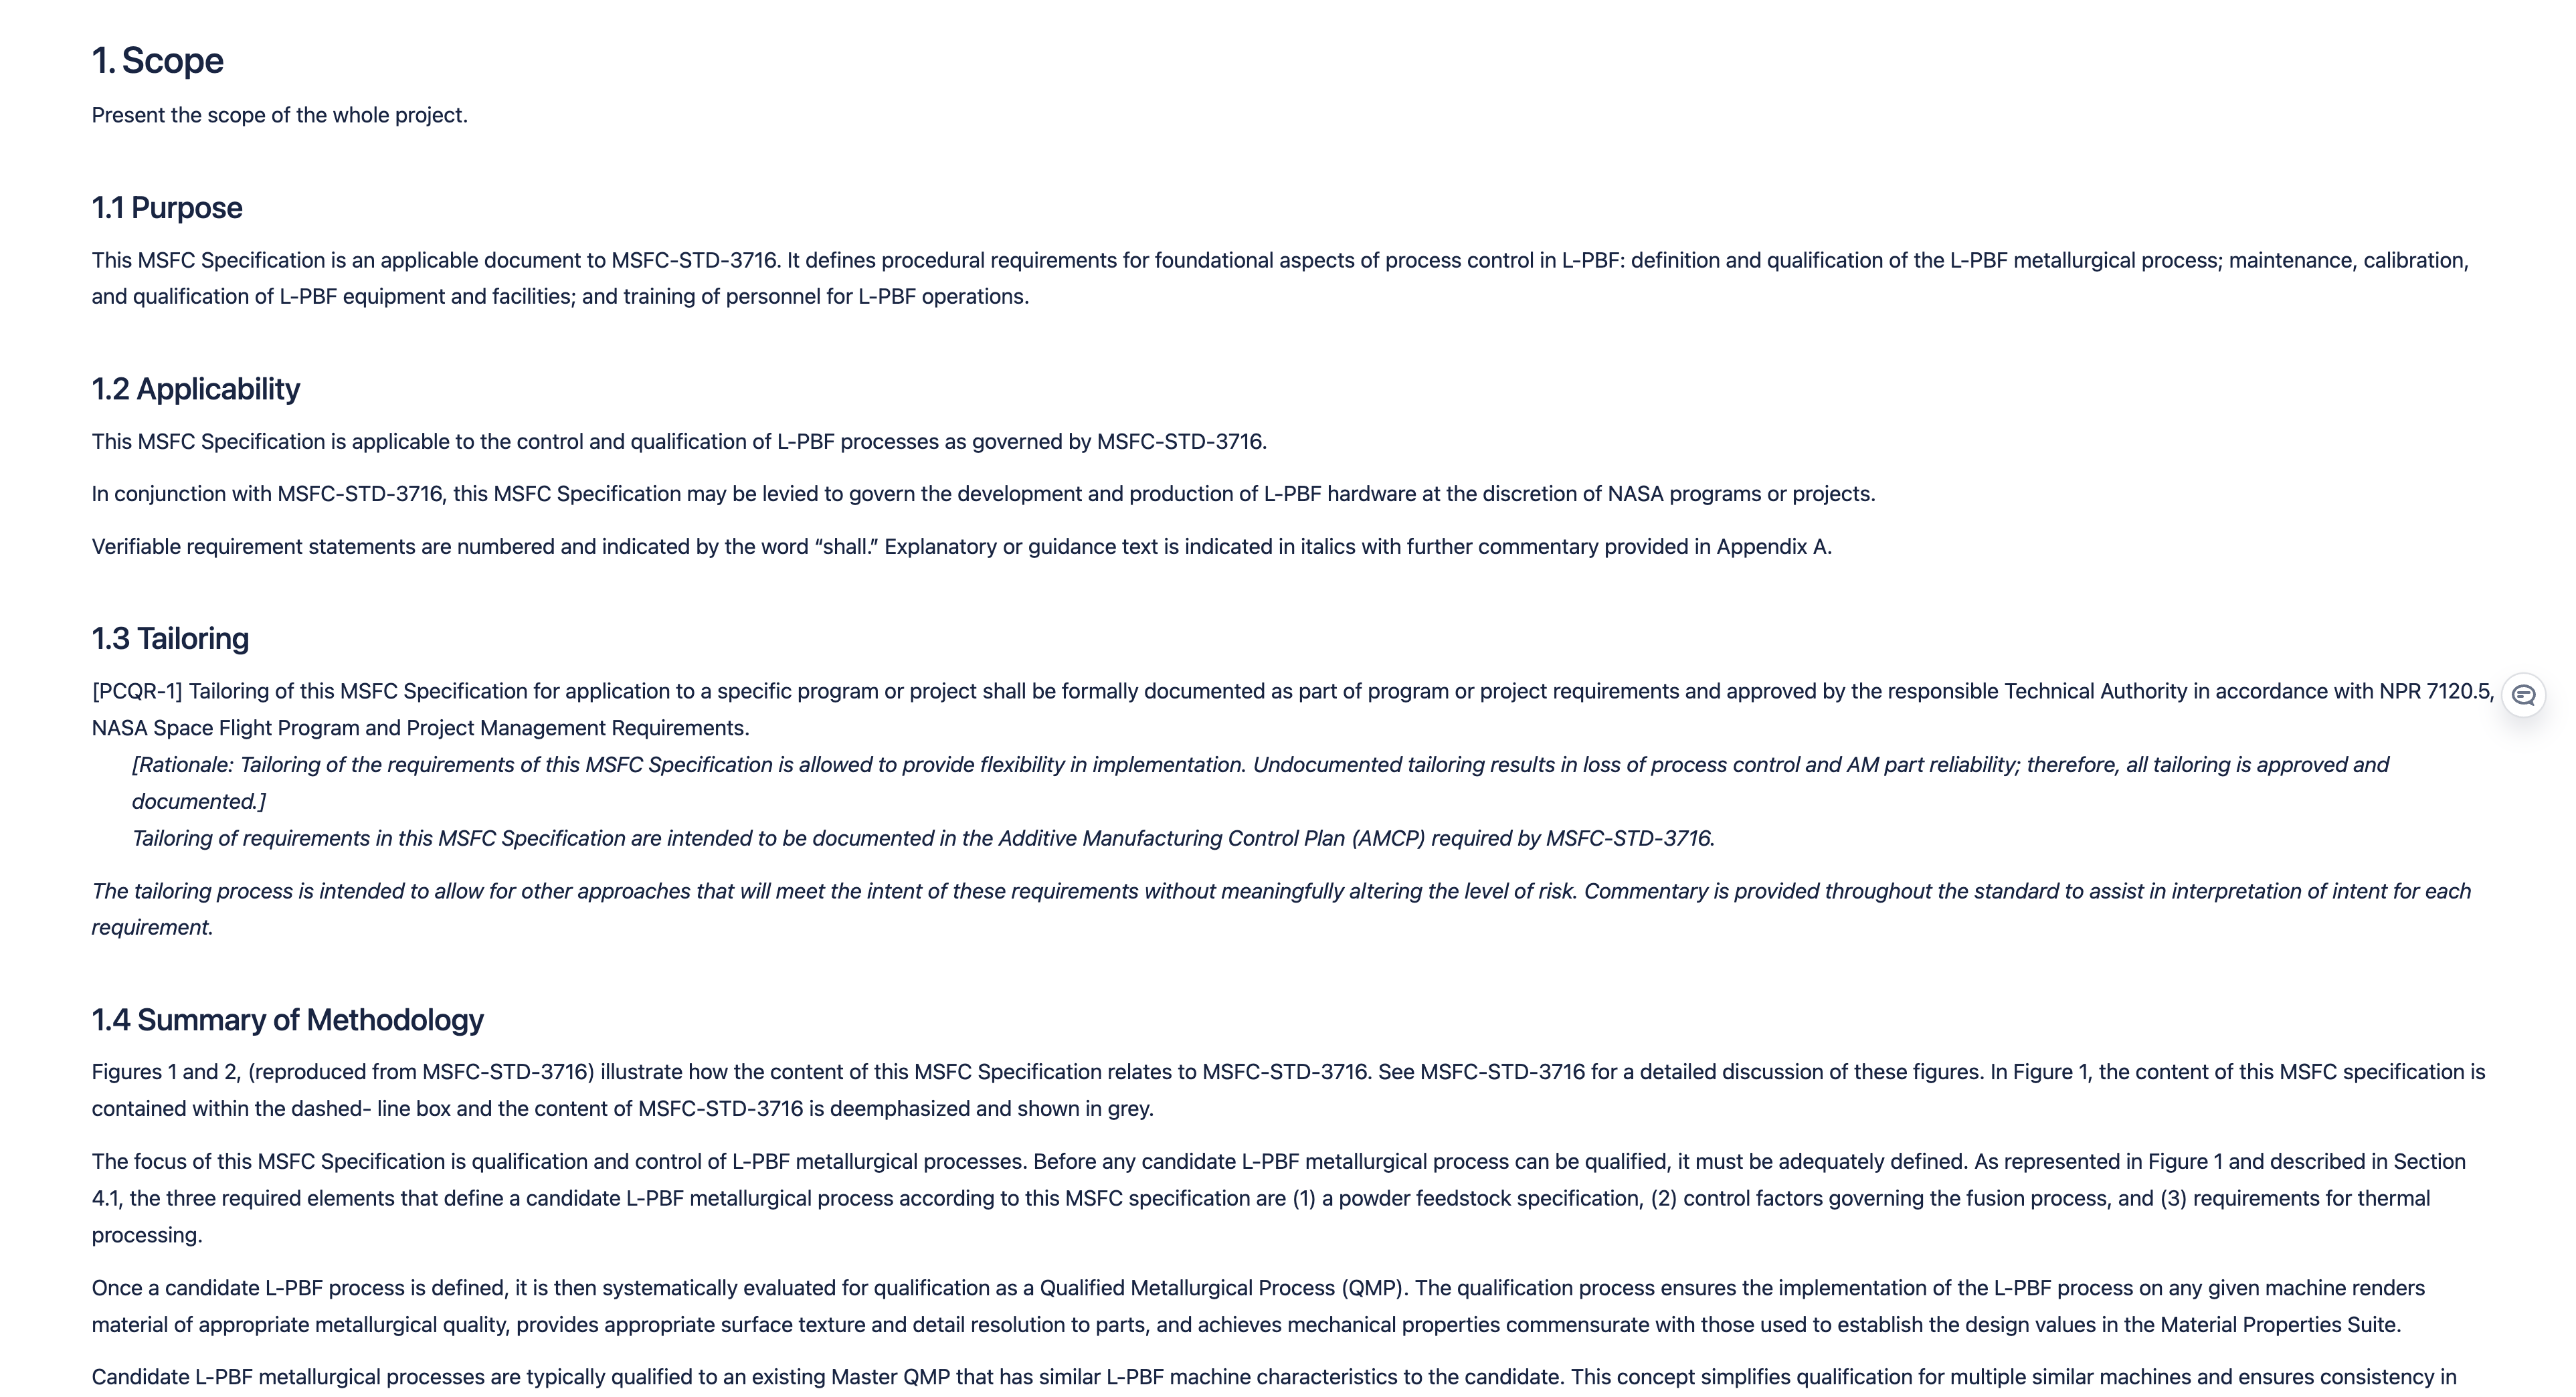
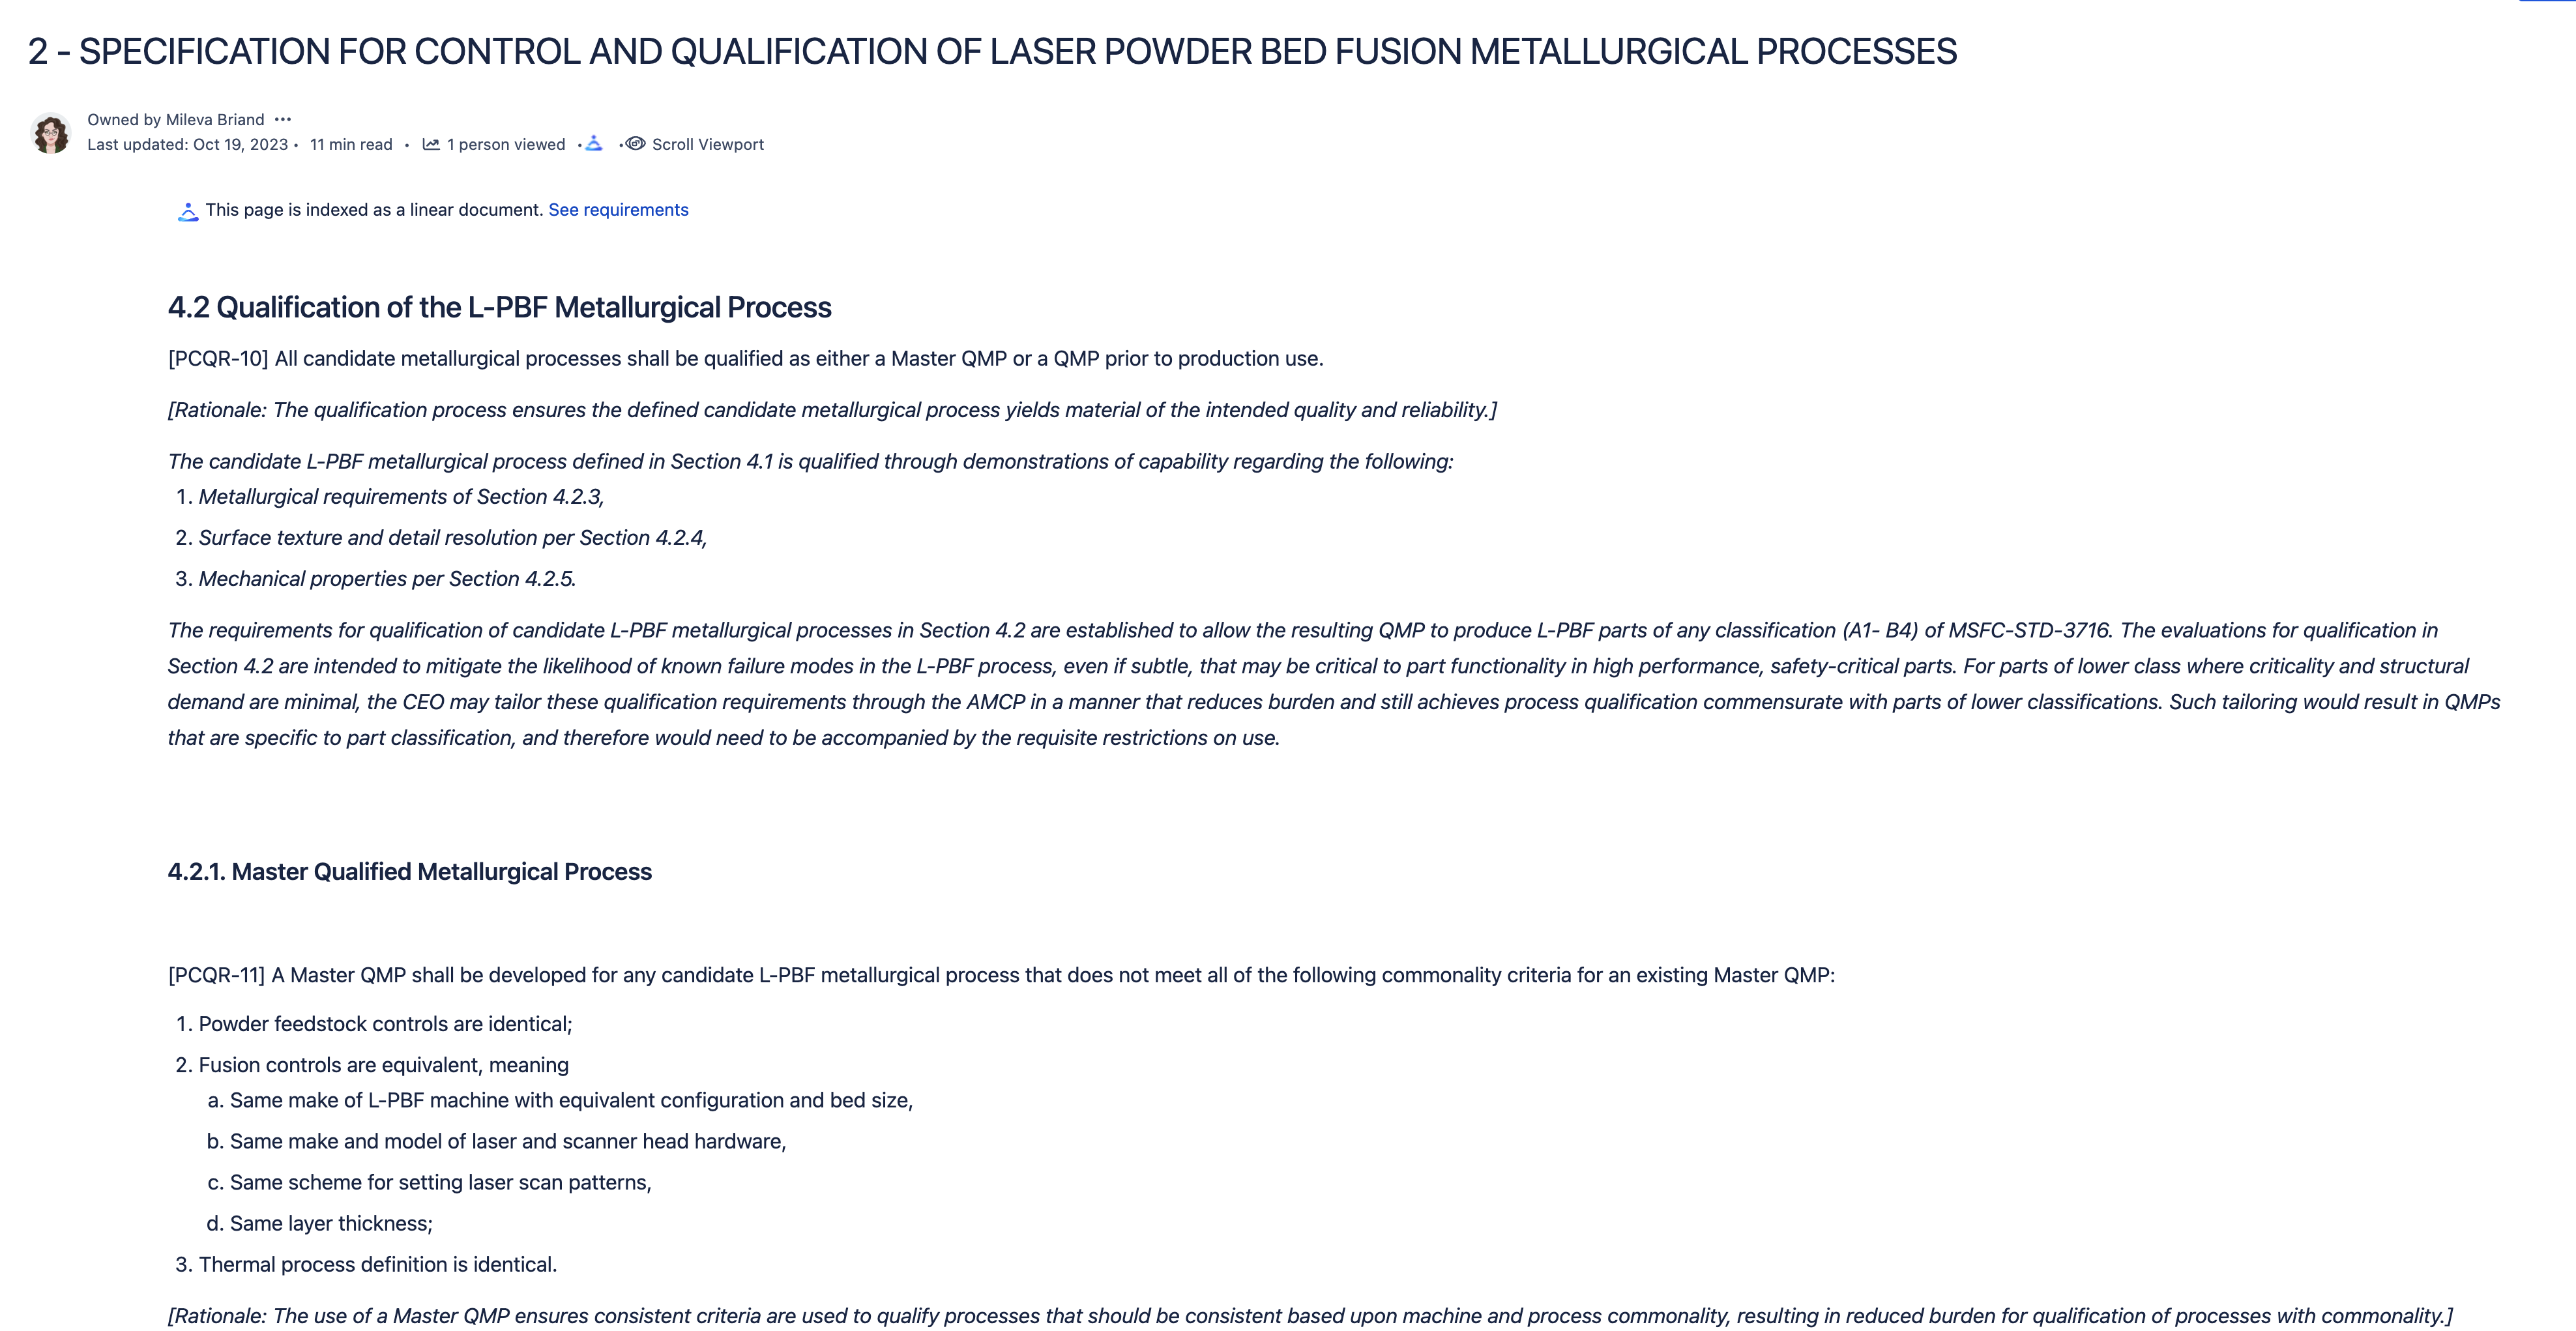
Instead of writing requirements in tables, some companies write long documents with titles and paragraphs. We coined the term “Linear documents” to designate such documents. For example, all ISO standards are formatted as linear documents.
|
What your document looks like: |
|
Are “linear documents” a standard?
No. However, IEEE, ISO and many others use similar-looking documents:
-
ISO/IEC publishes their directives for document formats: https://www.iso.org/directives-and-policies.html
-
IEEE publishes a preferred style for proposed IEEE standards, the IEEE SA Standards Style Manual.
Therefore we’ve specified “linear documents” below to unify the rules for our software.
Is there a template of linear documents?
There are no official templates, but there are examples:
-
ISO publishes a Word template on this page: https://www.iso.org/iso-templates.html
Where are “linear documents” specified?
In the next section below.
Specifications for linear documents
Structure
The most expected structure is:
-
Foreword
-
Introduction
-
1. Scope
-
2. References
-
3. Terms and definitions
-
A series of paragraphs, each preceded by the keyword as the subtitle for this paragraph.
-
-
4. (First body title of the document)
-
4.1 Subtitle
-
Paragraph
-
4.1.1 Grand-child
-
Paragraph
-
4.1.1.1 Fourth-level child
-
Paragraphs
-
-
…
-
A. Annex
-
…
-
Bibliography
How we parse
-
We’ll try to be as lenient as possible and give control to the user,
-
We’ll ignore the “Foreword” and “Introduction” etc.
-
We’ll put the prefix of the document before numbers like “4.1.1.1”, so the requirement key will be “DOC-4.1.1.1” and the text will be “Fourth-level child”,
-
We’ll consider DOC-4.1.1.1 as a child of DOC-4.1.1, and we will materialize it with a dependency, named @Section, to DOC-4.1.1. We’ll also materialize it with a plain text property named @Section (as well) which contains the titles:
4. Top title 4.1 Subtitle 4.1.1 Grand-child -
The last level of paragraphs are actual requirements. The intermediate levels only represent necessary boilerplate. To distinguish them and assist with searching, DOC-4.1.1.1 will have a property @Leaf = true.
Leniency
Since those documents are written by a variety of actors, we’ll support the following variations:
-
If titles are not numbered in the document, then we offer the option to add those numbers.
-
If titles are not numbered with actual numbers, we support uppercase and lowercase letters (A, a). We don’t support roman numbers for the moment (
IV, iv). -
If some titles are unimportant / irrelevant, then we offer the option to selectively ignore them.
-
If documents are spread out on several material pages (such as Confluence documents), then we offer to restart the numbering from a provided subsection.